Station 4 · Lesson 3
Running ICA
eeglab_data.set (D1) · Already applied: High-pass & low-pass filtering, Removing line noise (50/60 Hz), Bad channels, Channel interpolation, Re-referencingDownload the data (opens in a new tab)Script to reach this state
[ALLEEG, EEG, CURRENTSET, ALLCOM] = eeglab;
eeglabRoot = fileparts(which('eeglab'));
EEG = pop_loadset('eeglab_data.set', fullfile(eeglabRoot, 'sample_data'));
fullLocs = EEG.chanlocs;

% Main dataset: high-pass at 0.1 Hz, then 60 Hz line-noise removal
EEG = pop_eegfiltnew(EEG, 'locutoff', 0.1);
EEG = pop_eegfiltnew(EEG, 'locutoff', 58, 'hicutoff', 62, 'revfilt', 1);

% Bad channels you removed earlier, e.g. {'T7'}; leave empty if none
badChans = {};
if ~isempty(badChans)
    EEG = pop_select(EEG, 'rmchannel', badChans);
    EEG = pop_interp(EEG, fullLocs, 'spherical');
end

% Average reference, EOG channels excluded
eogIdx = find(ismember({EEG.chanlocs.labels}, {'EOG1', 'EOG2'}));
EEG = pop_reref(EEG, [], 'exclude', eogIdx);
EEG.filename = ''; EEG.filepath = ''; EEG.datfile = ''; EEG.saved = 'no';
[ALLEEG, EEG, CURRENTSET] = pop_newset(ALLEEG, EEG, 0, 'setname', 'D1 main', 'gui', 'off');
eeglab redraw;
Your browser's back button takes you to the exact place you were, so open anything you like.
The idea in brief
Every channelThe signal recorded from one electrode, as shown in EEGLAB. records a mix of sources: brain activity, eye blinks, muscles, and the heart. independent componentOne independent source from ICA, with its own scalp map and time series. analysis (ICAA method that separates the recording into independent sources, some brain and some artifact.) unmixes this into separate sources, each called an ICA component.
You then remove the artifactA non-brain signal mixed into the recording, such as blinks or muscle activity. components, meaning the non-brain signals, and keep the rest. You do not remove any channel or any part of the recording.
Before and after
Running ICA alone does not change your signalValues that change over time, such as the voltage recorded on a channel.. You see the before-and-after effect in the ICLabelA tool that classifies each ICA component into seven classes with a probability for each. lesson.

What does this show?
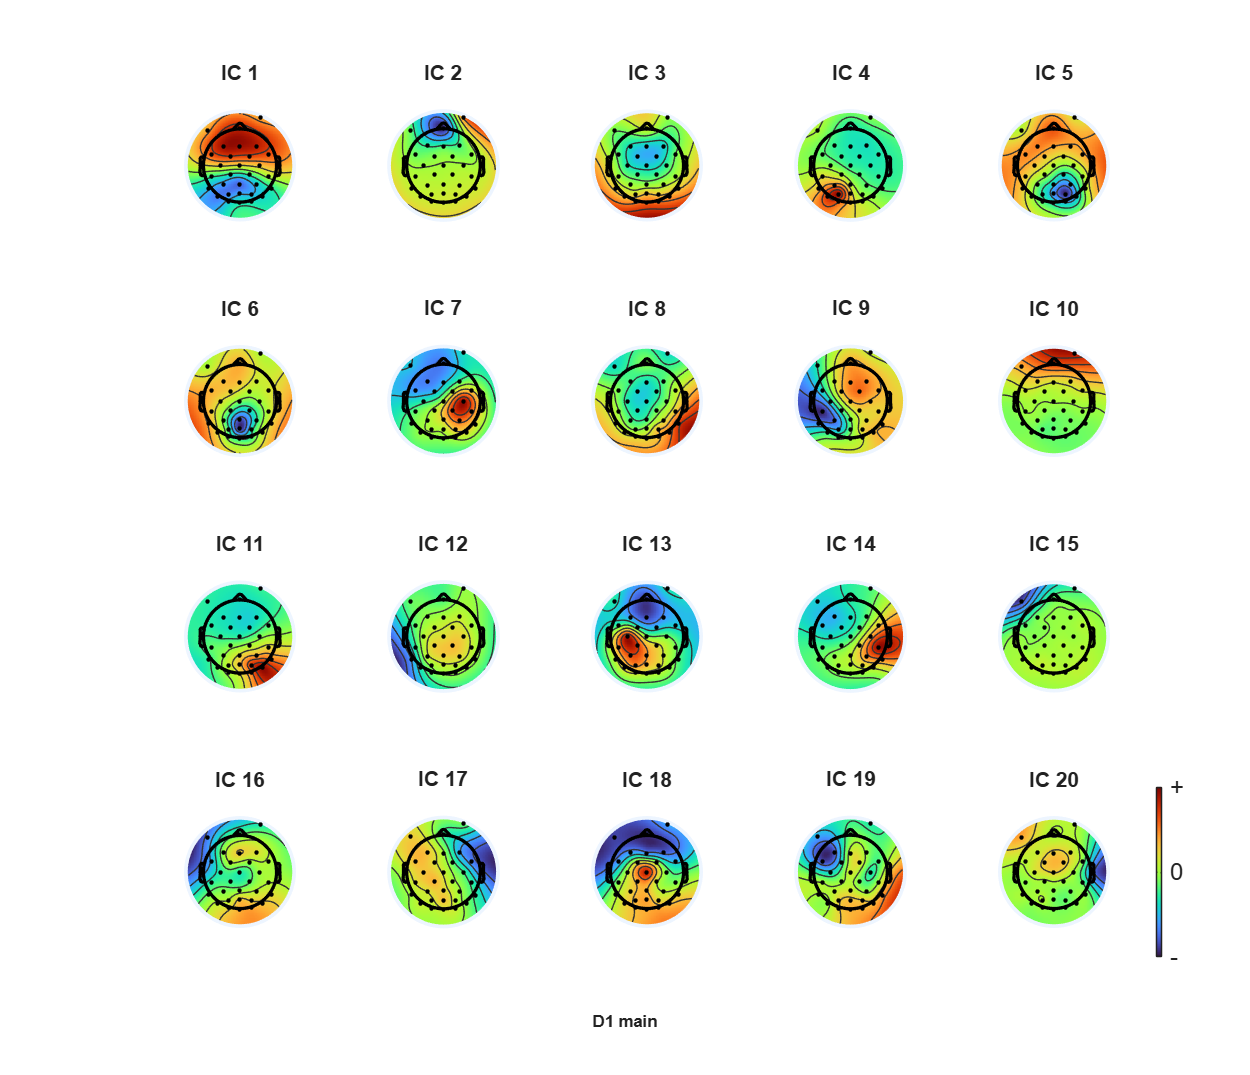
What does this show?
Your next questions, each answered in its own section:
Why do I need this step?
The reasons in detail, and the terms you need
In this lesson you only run ICA. Classifying and removing components is the ICLabel lesson.
The reason is that slow drift confuses ICA, and the official tutorial says decompositions are notably higher quality with a high-passA filter that passes high frequencies and weakens slow drifts. above 1 Hz. But a 1 Hz filterA tool that weakens some frequencies in a signal and keeps others. distorts slow ERP components such as P3.
The solution is two copies of the same data:
- The ICA copy, filtered at 1 Hz, used only to compute ICA.
- The main datasetOne EEG data file loaded in EEGLAB together with its information., filtered at 0.1 Hz, which receives the ICA result and carries on to the analysis.
The ICA result is a set of weights, a fixed way of combining channels. That is why it is valid to apply it to the main dataset, as the official tutorial explains.
Why do I need this step?
In this lesson you only run ICA. Classifying and removing components is the ICLabel lesson.
The reason is that slow drift confuses ICA, and the official tutorial says decompositions are notably higher quality with a high-pass above 1 Hz. But a 1 Hz filter distorts slow ERP components such as P3.
The solution is two copies of the same data:
- The ICA copy, filtered at 1 Hz, used only to compute ICA.
- The main dataset, filtered at 0.1 Hz, which receives the ICA result and carries on to the analysis.
The ICA result is a set of weights, a fixed way of combining channels. That is why it is valid to apply it to the main dataset, as the official tutorial explains.
How do I do it in EEGLAB?
16 steps in the menus
Start with the main dataset loaded, as in the Starting point. We call it dataset 1.
First: create the ICA copy
- Make sure dataset 1 is current in the Datasets .
- Open Tools then Filter the data then Basic FIR filter (new, default).
- In Lower edge of the frequency pass band (Hz), type
1. Leave the other fields as they are and press OK. - Name the new dataset
D1 ica1hzand leave Overwrite it in memory (set=yes; unset=create a new dataset) unchecked. You now have dataset 2, and dataset 1 is unchanged.
Why 1 Hz on top of 0.1 Hz?
The main dataset is already filtered at 0.1 Hz. A 1 Hz filter on top of it gives almost the same result as filteringApplying a filter to the data. the raw data at 1 Hz, because the higher filter decides what remains.
Why 1 Hz on top of 0.1 Hz?
The main dataset is already filtered at 0.1 Hz. A 1 Hz filter on top of it gives almost the same result as filteringApplying a filter to the data. the raw data at 1 Hz, because the higher filter decides what remains.
Second: run ICA on the ICA copy
- With dataset 2 current, open Tools then Decompose data by ICA.
- In ICA algorithm to use (click to select), keep the first option, Extended Infomax (runica.m; default). The options field below shows
'extended', 1. - Keep Reorder components by variance (if that’s not already the case) checked, leave Use only channel type(s) or indices empty, and press OK.
- A window may say that the data rank is lower than the number of channels, with a Proposed rank: field. Compare it with the expected rank: the number of channels, minus the interpolated channels, minus 1 for the average reference. In D1 it is 31 out of 32. If the number differs, type the expected one, then press OK.
- Wait. The command window prints the training steps, which can take from under a minute to a few minutes depending on your computer.
Third: display the component maps
- Open Plot then Component maps then In 2-D and keep the defaults.
- Look for the blink component: a strong map at the front of the head, symmetric between left and right. It is usually among the first components.
Fourth: copy the weights to the main dataset
- Go back to dataset 1 from the Datasets menu.
- Open Edit then Dataset info.
- Next to ICA weights array or text/binary file (if any):, press from other dataset, type
2, then OK. Three fields fill in automatically:ALLEEG(2).icaweights,ALLEEG(2).icasphere, andALLEEG(2).icachansind. - Press OK to close the window.
- Save the main dataset with File then Save current dataset as. The ICLabel lesson starts from it.
How do I do it in EEGLAB?
Start with the main dataset loaded, as in the Starting point. We call it dataset 1.
First: create the ICA copy
- Make sure dataset 1 is current in the Datasets menu.
- Open Tools then Filter the data then Basic FIR filter (new, default).
- In Lower edge of the frequency pass band (Hz), type
1. Leave the other fields as they are and press OK. - Name the new dataset
D1 ica1hzand leave Overwrite it in memory (set=yes; unset=create a new dataset) unchecked. You now have dataset 2, and dataset 1 is unchanged.
Why 1 Hz on top of 0.1 Hz?
The main dataset is already filtered at 0.1 Hz. A 1 Hz filter on top of it gives almost the same result as filtering the raw data at 1 Hz, because the higher filter decides what remains.
Why 1 Hz on top of 0.1 Hz?
The main dataset is already filtered at 0.1 Hz. A 1 Hz filter on top of it gives almost the same result as filtering the raw data at 1 Hz, because the higher filter decides what remains.
Second: run ICA on the ICA copy
- With dataset 2 current, open Tools then Decompose data by ICA.
- In ICA algorithm to use (click to select), keep the first option, Extended Infomax (runica.m; default). The options field below shows
'extended', 1. - Keep Reorder components by variance (if that’s not already the case) checked, leave Use only channel type(s) or indices empty, and press OK.
- A window may say that the data rank is lower than the number of channels, with a Proposed rank: field. Compare it with the expected rank: the number of channels, minus the interpolated channels, minus 1 for the average reference. In D1 it is 31 out of 32. If the number differs, type the expected one, then press OK.
- Wait. The command window prints the training steps, which can take from under a minute to a few minutes depending on your computer.
Third: display the component maps
- Open Plot then Component maps then In 2-D and keep the defaults.
- Look for the blink component: a strong map at the front of the head, symmetric between left and right. It is usually among the first components.
Fourth: copy the weights to the main dataset
- Go back to dataset 1 from the Datasets menu.
- Open Edit then Dataset info.
- Next to ICA weights array or text/binary file (if any):, press from other dataset, type
2, then OK. Three fields fill in automatically:ALLEEG(2).icaweights,ALLEEG(2).icasphere, andALLEEG(2).icachansind. - Press OK to close the window.
- Save the main dataset with File then Save current dataset as. The ICLabel lesson starts from it.
How do I write it as code?
The same steps in 22 lines of MATLAB
% Main dataset (high-pass 0.1 Hz, line noise removed, average reference) is in EEG
EEG_main = EEG;

% ICA copy: same data, high-pass at 1 Hz
EEG_ica = pop_eegfiltnew(EEG_main, 'locutoff', 1);
EEG_ica.setname = 'D1 ica1hz';

% Expected rank: channels - interpolated channels - 1 (average reference)
expectedRank = EEG_ica.nbchan - numel(badChans) - 1;
fprintf('Expected data rank: %d\n', expectedRank);

% Extended Infomax on the ICA copy
EEG_ica = pop_runica(EEG_ica, 'icatype', 'runica', 'extended', 1);
% If "Data rank (N)" is missing or N differs from expectedRank, run instead:
% EEG_ica = pop_runica(EEG_ica, 'icatype', 'runica', 'extended', 1, 'pca', expectedRank);

% Copy the decomposition back to the main dataset
EEG_main.icaweights  = EEG_ica.icaweights;
EEG_main.icasphere   = EEG_ica.icasphere;
EEG_main.icachansind = EEG_ica.icachansind;
EEG_main.icawinv     = [];   % recomputed by eeg_checkset
EEG_main.icaact      = [];
EEG = eeg_checkset(EEG_main);

% Scalp maps of the first 20 components
pop_topoplot(EEG, 0, 1:20);

EEG = pop_saveset(EEG, 'filename', 'D1_main_ica.set', 'filepath', pwd);
In a script, the rank window does not appear. pop_runica tries to detect the reduced rank, but its estimate can fail. When it detects it, it prints a line such as Data rank (31) is smaller than the number of channels (32). Compare that number with the Expected data rank the script printed. If the line is missing or the numbers differ, use the commented line that passes 'pca' with the expected value. If your data has bad channels, for example 32 channels with 2 interpolated, the expected rank is 29.
The two-copy method
The full explanation of the two-copy method, and when you need 2 Hz instead of 1, is in the next lesson: 1-Hz filtering for ICA & copying weights.
The two-copy method
The full explanation of the two-copy method, and when you need 2 Hz instead of 1, is in the next lesson: 1-Hz filtering for ICA & copying weights.
How do I write it as code?
% Main dataset (high-pass 0.1 Hz, line noise removed, average reference) is in EEG
EEG_main = EEG;

% ICA copy: same data, high-pass at 1 Hz
EEG_ica = pop_eegfiltnew(EEG_main, 'locutoff', 1);
EEG_ica.setname = 'D1 ica1hz';

% Expected rank: channels - interpolated channels - 1 (average reference)
expectedRank = EEG_ica.nbchan - numel(badChans) - 1;
fprintf('Expected data rank: %d\n', expectedRank);

% Extended Infomax on the ICA copy
EEG_ica = pop_runica(EEG_ica, 'icatype', 'runica', 'extended', 1);
% If "Data rank (N)" is missing or N differs from expectedRank, run instead:
% EEG_ica = pop_runica(EEG_ica, 'icatype', 'runica', 'extended', 1, 'pca', expectedRank);

% Copy the decomposition back to the main dataset
EEG_main.icaweights  = EEG_ica.icaweights;
EEG_main.icasphere   = EEG_ica.icasphere;
EEG_main.icachansind = EEG_ica.icachansind;
EEG_main.icawinv     = [];   % recomputed by eeg_checkset
EEG_main.icaact      = [];
EEG = eeg_checkset(EEG_main);

% Scalp maps of the first 20 components
pop_topoplot(EEG, 0, 1:20);

EEG = pop_saveset(EEG, 'filename', 'D1_main_ica.set', 'filepath', pwd);
In a script, the rank window does not appear. pop_runica tries to detect the reduced rank, but its estimate can fail. When it detects it, it prints a line such as Data rank (31) is smaller than the number of channels (32). Compare that number with the Expected data rank the script printed. If the line is missing or the numbers differ, use the commented line that passes 'pca' with the expected value. If your data has bad channels, for example 32 channels with 2 interpolated, the expected rank is 29.
The two-copy method
The full explanation of the two-copy method, and when you need 2 Hz instead of 1, is in the next lesson: 1-Hz filtering for ICA & copying weights.
The two-copy method
The full explanation of the two-copy method, and when you need 2 Hz instead of 1, is in the next lesson: 1-Hz filtering for ICA & copying weights.
Which value should I choose?
Suitable values for your analysis goal
| Setting | Value | Why |
|---|---|---|
| High-pass for the ICA copy | 1 Hz, or 2 if components stay ambiguous | Official tutorial: ICA quality is notably higher above 1 Hz, sometimes 2 (RunICA page). |
| Algorithm | Extended Infomax (runica) | The default in EEGLAB 2026.1, used in the official tutorial. Alternatives such as AMICA and Picard are in an optional lesson. |
| Channels | All EEG channels. In D1 we keep EOG1 and EOG2 | The two eye channels record the same blinks we want to isolate, and the official tutorial runs ICA on all 32 channels of D1. |
| Number of components | Equal to the data rank: 31 in D1 after average reference | Average reference reduces the rank by one, and ICA does not behave well when asked for more components than the rank (RunICA page). |
Which value should I choose?
| Setting | Value | Why |
|---|---|---|
| High-pass for the ICA copy | 1 Hz, or 2 if components stay ambiguous | Official tutorial: ICA quality is notably higher above 1 Hz, sometimes 2 (RunICA page). |
| Algorithm | Extended Infomax (runica) | The default in EEGLAB 2026.1, used in the official tutorial. Alternatives such as AMICA and Picard are in an optional lesson. |
| Channels | All EEG channels. In D1 we keep EOG1 and EOG2 | The two eye channels record the same blinks we want to isolate, and the official tutorial runs ICA on all 32 channels of D1. |
| Number of components | Equal to the data rank: 31 in D1 after average reference | Average reference reduces the rank by one, and ICA does not behave well when asked for more components than the rank (RunICA page). |
How do I check it worked?
5 quick checks
- In the main EEGLAB window, with dataset 1 current, ICA weights should show Yes.
- In the command window, type
size(EEG.icawinv). In D1 without interpolated channels it shows32 31: 32 channels and 31 ICA components. Each interpolated channel reduces the number of components by one. - Open the component maps with Plot then Component maps then In 2-D on dataset 1. You should see the same maps as on the ICA copy, including the blink component.
- Reload the saved file with File then Load existing dataset, and check that ICA weights still shows Yes.
- The rank matches: the
Data rankthatpop_runicaprinted equals theExpected data rank. In D1 both are 31.
How do I check it worked?
- In the main EEGLAB window, with dataset 1 current, ICA weights should show Yes.
- In the command window, type
size(EEG.icawinv). In D1 without interpolated channels it shows32 31: 32 channels and 31 ICA components. Each interpolated channel reduces the number of components by one. - Open the component maps with Plot then Component maps then In 2-D on dataset 1. You should see the same maps as on the ICA copy, including the blink component.
- Reload the saved file with File then Load existing dataset, and check that ICA weights still shows Yes.
- The rank matches: the
Data rankthatpop_runicaprinted equals theExpected data rank. In D1 both are 31.
What mistakes do people make?
5 mistakes and how to avoid them
- Computing ICA on 0.1 Hz data, or continuing the ERP on the 1 Hz copy. The first gives a weaker decomposition, the second distorts P3 and N400. The two copies together are the solution.
- Trusting the automatic rank estimate.
pop_runicatries to detect the rank, but the estimate can fail. Signs of a missed rank: several components that look almost identical or like pure noise, or ICA that does not converge. Always compare the printedData rankwith the expected rank (channels minus interpolated channels minus 1). If they differ, type'pca', 31in the options field, with your expected number instead of 31. - Non-brain channels slipping in by accident. Exclude EOG and ECG channels according to your goal, and never let them in without a decision. Use Use only channel type(s) or indices to choose the channels. In D1 we decided to keep the two eye channels for a clear reason.
- Expecting the same result every time. ICA shuffles the data order at random during training, so the order and shape of components vary slightly between runs. Your component order may not match the picture in this lesson: the blink may be component 1 here and component 3 for you. Find a component by its shape, not its number.
- Changing the reference after ICA. The weights are tied to the reference used when ICA was computed. Re-reference before ICA and leave it unchanged afterward. EEGLAB itself warns you if you change it.
What mistakes do people make?
- Computing ICA on 0.1 Hz data, or continuing the ERP on the 1 Hz copy. The first gives a weaker decomposition, the second distorts P3 and N400. The two copies together are the solution.
- Trusting the automatic rank estimate.
pop_runicatries to detect the rank, but the estimate can fail. Signs of a missed rank: several components that look almost identical or like pure noise, or ICA that does not converge. Always compare the printedData rankwith the expected rank (channels minus interpolated channels minus 1). If they differ, type'pca', 31in the options field, with your expected number instead of 31. - Non-brain channels slipping in by accident. Exclude EOG and ECG channels according to your goal, and never let them in without a decision. Use Use only channel type(s) or indices to choose the channels. In D1 we decided to keep the two eye channels for a clear reason.
- Expecting the same result every time. ICA shuffles the data order at random during training, so the order and shape of components vary slightly between runs. Your component order may not match the picture in this lesson: the blink may be component 1 here and component 3 for you. Find a component by its shape, not its number.
- Changing the reference after ICA. The weights are tied to the reference used when ICA was computed. Re-reference before ICA and leave it unchanged afterward. EEGLAB itself warns you if you change it.
Your browser doesn't allow saving progress. All lessons are open, but completion marks won't be saved.
Done. Your progress is saved in this browser.UndoHow do I write it in my paper?
A Methods template: edit the data, settings and versions to match what you ran
A template: edit the data, settings and versions to match what you ran.
Independent component analysis (extended Infomax; Lee et al., 1999) was computed with runica ([31] components after PCA reduction to the data rank) on a copy of the data high-pass filtered at 1 Hz, and the resulting weights were applied to the 0.1 Hz high-pass filtered data.How do I write it in my paper?
A template: edit the data, settings and versions to match what you ran.
Independent component analysis (extended Infomax; Lee et al., 1999) was computed with runica ([31] components after PCA reduction to the data rank) on a copy of the data high-pass filtered at 1 Hz, and the resulting weights were applied to the 0.1 Hz high-pass filtered data.Where can I read more?
5 sources, official docs first
- EEGLAB TutorialDocumentation6. Reject artifacts > d. Indep. Comp. Analysis: Running ICA decompositions
- EEGLAB TutorialDocumentationHow to deal with the aggressive high-pass filter applied before running ICA
- EEGLAB TutorialDocumentationIssues with data rank deficiencies
- Luck, Applied Event-Related Potential Data Analysis (1st edition)Chapter 9: Artifact Correction with ICA
- ICA applied to EEG part 7: Running ICA in EEGLAB and visualizing componentsVideoFull video · 11:55
Written for EEGLAB 2026.1 · 2026-10-28
Going further
- EEGLAB Tutorial: https://eeglab.org/tutorials/06_RejectArtifacts/RunICA.html (6. Reject artifacts > d. Indep. Comp. Analysis: Running ICA decompositions)
- EEGLAB Tutorial: https://eeglab.org/tutorials/06_RejectArtifacts/RunICA.html (How to deal with the aggressive high-pass filter applied before running ICA)
- EEGLAB Tutorial: https://eeglab.org/tutorials/06_RejectArtifacts/RunICA.html (Issues with data rank deficiencies)
- Luck, Applied Event-Related Potential Data Analysis (1st edition): https://socialsci.libretexts.org/Bookshelves/Psychology/Biological_Psychology/Applied_Event-Related_Potential_Data_Analysis_(Luck) (Chapter 9: Artifact Correction with ICA)
- ICA applied to EEG part 7: Running ICA in EEGLAB and visualizing components: https://www.youtube.com/watch?v=2hrYEYSycGI (Full video)
Need help?
Ask, share feedback, or report an error
- Report a scientific error · Needs a GitHub account. Don't have one? Use "Share your thoughts".